News & insights

Insights, news, and Kubernetes field notes.

How Ruckos LB moves a packet: XDP, direct return, IP-in-IP and BGP

One stable address for a service, spread across its replicas on any host, for any TCP or UDP protocol. Here is the path a packet takes, header by header.

Ruckos LB is the load balancer built into Ruckos Linux. A service gets one address from a range you set once for the cluster. Its replicas can run on any host, and a failed replica or a lost host drops out without the address moving. This post follows one connection through it.

1. The decision is made at the network card

Each host loads a small eBPF program at the XDP hook of its network card. XDP runs on a packet as soon as the driver has it, so the choice of replica is made before the packet goes any further into the host. The node API loads the program and fills its lookup tables; the program only ever reads those tables.

Inside one hostA packet for a service address arrives at the network card. The XDP program checks its connection cache, and for a new connection picks a healthy replica from a hash ring. A replica on this host gets the packet with its destination MAC rewritten. A replica on another host gets it wrapped in IP-in-IP. Network cardpacket arrives Ruckos LB, an XDP program 1. Connection cacheseen this connection before? 2. Hash ringnew: pick a healthy replica Replica hereon this host Another hostthat runs the replica MAC rewritten IP-in-IP
The decision is made at the network card, before the packet goes any further into the host.

The program does two lookups. First a connection cache of 65,536 entries, keyed on the connection's source and destination addresses, ports and protocol. If the connection is already there, the packet goes to the replica it has been using. An open connection stays on its replica for as long as that replica lives.

2. A new connection is hashed onto a ring

A connection that is not in the cache is hashed into a ring of 4,093 slots for that address, filled with the service's healthy replicas using Maglev consistent hashing. The ring is built over container names, so every host builds the same ring and makes the same choice for the same connection. It does not matter which host a packet arrives at.

The hash ring before and after a replica failsA row of slots, each owned by web-1, web-2 or web-3. When web-2 fails its health check, only the slots it owned are handed to web-1 or web-3. Every other slot keeps its owner. All three healthy web-2 fails its health check web-1web-2web-3slot that changed hands
Only the failed replica's slots change hands. Connections to the other replicas keep landing where they did.

When a replica fails or a new one starts, most of the ring stays as it was. Together with the connection cache, that means a change disturbs only the connections that were on the replica that went away.

3. Delivery, on this host or another

If the chosen replica is on the same host, the program rewrites the packet's destination MAC to the container's and passes it on; the host's bridge delivers it. If the replica is on another host, the program puts an outer IPv4 header in front of the packet, addressed to that host, and sends it back out of the card. The receiving host removes the outer header and delivers the original packet to its own replica.

The packet headers at each stepAs it arrives, the packet is addressed from the client to the service address. Delivered to a replica on the same host, only the Ethernet destination changes. Sent to another host, an outer IP header from host 1 to host 2 is added in front and the original is untouched. The reply goes from the service address to the client. As it arrives Ethernetto the host IP198.51.100.7 → 203.0.113.1 TCP:443 To a replica here Ethernetto the container IP198.51.100.7 → 203.0.113.1 TCP:443 To another host Ethernetnext hop Outer IP, addedhost 1 → host 2 IP198.51.100.7 → 203.0.113.1 TCP:443 The reply Ethernetto the gateway IP203.0.113.1 → 198.51.100.7 TCP:443
The client and service addresses are never rewritten. Orange marks what changed or was added.

In both cases the original packet is untouched: it still goes from the client to the service address. Each container behind an address holds that address on its loopback interface and is set never to answer ARP for it, so it accepts the packet as its own.

The outer header costs 20 bytes. For TCP, the host caps the segment size a replica offers in its handshake (1,440 bytes on a 1,500-byte network), so wrapped packets always fit. UDP has no handshake to adjust, so a UDP service needs jumbo frames between hosts or datagrams small enough to fit.

4. The reply goes straight back

The replica answers with the service address as its source, out through the host's bridge to the gateway. The reply never passes back through the load balancer, and nothing is translated on either path, so the application sees the real client address.

The reply pathThe request goes from the client through Ruckos LB to the replica web-1. The reply goes from web-1 straight back to the client and does not pass through the load balancer again. Client198.51.100.7 Host Ruckos LBpicks a replica web-1holds the address request reply: straight back, no second pass through the load balancer
Direct server return: the load balancer handles the request only.

This is direct server return. The load balancer does work only on the request, which is usually the smaller half of a connection.

5. How the address reaches your network

There are two ways, chosen per cluster to fit the network you have.

Two ways the address reaches your networkWith BGP, every host with a healthy replica announces the service address to your switches, which spread flows across all of them. With layer 2, one owner host answers ARP for the address and the other hosts stand by to take over. BGPEvery host with a healthy replica announces it Your switches Host 1announces Host 2announces Host 3announces Layer 2One owner answers ARP, held by a lease Your switches Host 1owner Host 2standby Host 3standby
With BGP, flows arrive at every host. With layer 2, they arrive at the owner, which still spreads them across every replica.

BGP. Each host runs a BGP speaker inside the node API and announces a service address only while it has a healthy replica of it. Your switches install equal-cost routes and spread flows across the hosts. BFD on each session detects a lost host in well under a second. When a host is drained, it withdraws its routes first, while IP-in-IP keeps serving the connections that still arrive. Hosts can share one AS number or have one each, and can peer by address or over unnumbered interfaces.

Layer 2. On a network without BGP, each address has one owner host, held by a lease. The owner answers ARP for the address and sends gratuitous ARP when it takes over. Everything for that address enters through the owner, which still spreads it across every replica, locally or over IP-in-IP. If the owner is lost, another host takes the lease within seconds. To spread arrivals across hosts in this mode, use more addresses: different hosts own different ones.

For BGP, the network needs to peer with the hosts and use equal-cost routes, allow BFD, accept replies whose source is a service address (loose reverse-path filtering), and pass requests and replies through the same firewall.

6. Health checks keep the ring honest

Each host checks the replicas it runs. A TCP connect every second marks a replica down after three failures in a row and back up after two passes. An optional HTTP check on a path you name runs every five seconds. A host acts on its own results at once and tells the others only when a replica changes state. The cluster's store is never in the packet path.

7. Three ways to balance

Spread hashes each connection on its own, so one client's connections land on different replicas. Sticky hashes on the client address, so one client always reaches the same replica. Primary puts a single replica in every slot of the ring, so all traffic goes to it, and a healthy standby takes over if it fails.

Try it

rctl weir range 192.168.1.11 10.100.0.1 10.100.0.254

rctl weir vip create 192.168.1.11 --service web --port 80 --port 443 --tier frontend

The test opens connections from your machine and reports which replica took each one. Replies come straight from the replica, so the client cannot tell from the reply alone; the test asks each host's connection cache instead. Here is a real run against a DNS service with three replicas on three hosts, set to spread:

rctl weir test
$ rctl weir test 192.168.1.11 dns --requests 20
Successful: Spread, the connections went to 3 containers.

20 connections to 10.100.0.1:53 from this PC (Spread)
   1  dns-2 on host-3
   2  dns-2 on host-3
   3  dns-2 on host-3
   4  dns-3 on host-2
   5  dns-2 on host-3
   6  dns-3 on host-2
   7  dns-2 on host-3
   8  dns-1 on host-1
   9  dns-3 on host-2
  10  dns-3 on host-2
  11  dns-1 on host-1
  12  dns-1 on host-1
  13  dns-2 on host-3
  14  dns-3 on host-2
  15  dns-1 on host-1
  16  dns-1 on host-1
  17  dns-1 on host-1
  18  dns-3 on host-2
  19  dns-2 on host-3
  20  dns-2 on host-3

   8 x  dns-2 on host-3
   6 x  dns-3 on host-2
   6 x  dns-1 on host-1

Twenty connections from one machine landed on all three replicas, eight, six and six. The same test is a button in Ruckos-V Manager, under the cluster's Load Balancer settings. More on the Ruckos LB page.
The Ruckos scheduler: say how many, and it keeps them running

Run N copies of an image as a service, and Ruckos places them, replaces the ones that are lost, resizes them live and upgrades them without the service going down.

A service on Ruckos Microservices is one record: an image, CPU and memory for each replica, a replica count, the store it lives on, an optional data disk, the load balancer it sits behind, and how you want it placed and upgraded. Each replica is an ordinary container made from that record, named and numbered: web-1, web-2, web-3. A new replica takes the lowest free number.

One scheduler, and why

The cluster has one scheduler at a time, held by a lease. Only the holder places or removes replicas; every host just starts and stops what is assigned to it. If the scheduler's host is lost, the lease expires and another host takes over within seconds. Letting every host decide for itself was ruled out for a simple reason: two hosts could each start the "third" replica.

The scheduler loopThe service web wants three replicas. The one scheduler for the cluster finds two running, web-1 on host 1 and web-2 on host 2, and places web-3 on host 3. Service: webwants 3 replicas Schedulerone per cluster, holds a lease Host 1runs web-1 Host 2runs web-2 Host 3web-3 placed here place wanted 3, found 2: place one more
Every few seconds, and at once on any change: compare what is wanted with what exists, and close the gap.

The count is taken over replicas that are assigned, starting or running, not only the healthy ones. Health decides what receives traffic and gates upgrades. If it decided the count too, a replica that was still starting would be replaced while it started. When there are too many, the newest replica is stopped. A replica that keeps failing to start is reported on the service, and is not retried in a tight loop.

Where a replica goes

Every placement runs the same checks: the host has the CPU and memory free, it mounts the service's store, it has every CPU feature the image needs, it is under the limit of replicas per host that you set, and it is not being drained. Among the hosts that pass, the one with the fewest replicas of this service wins, then the one with the most free memory.

Placement checks on three hostsHost 1 passes the fit, store and CPU feature checks but already holds the per-host limit of replicas, so it is skipped. Host 2 is being drained, so it is skipped. Host 3 passes every check and is chosen. Host 1 ✓CPU and memory fit ✓Store is mounted ✓CPU features match ✗Per-host limit reached Skipped Host 2 ✓CPU and memory fit ✓Store is mounted ✓CPU features match ✗Being drained Skipped Host 3 ✓CPU and memory fit ✓Store is mounted ✓CPU features match ✓Under the per-host limit Chosen
Every check has to pass. If no host passes, the replica is not placed and the service says why.

Placement matches CPU features, not CPU models. Two hosts a generation apart can share replicas as long as both have what the image needs, such as AVX2. A live move is stricter: the target must have every feature of the source, because a running process has already detected its CPU.

Resize without a restart

A container shares the host's kernel, so its CPU and memory limits can change while it runs. For a service, a change applies to every replica at once and to every replica started later. Two requests are refused: lowering memory below what a replica is using now, unless you explicitly override it, and raising CPU or memory on a host that has no room. Nothing is moved for you; you scale out, or drain or move the workload. For applications that size themselves at start, such as a JVM, you can ask for a rolling restart along with the change.

Storage that follows the replica

A service lives on a shared store that every host mounts, which is what lets a replica run on any host. Each replica can also have its own data disk on that store. When a host is lost, the replacement replica takes the name and the disk of the one it replaces. If that disk is damaged, a new one is created and the damaged one is kept and listed, with a delete action, until you remove it. Disks are deleted only when you scale down or delete the service.

When a host is lost

A lost host's replicas count as missing once its lease has gone and the host has been fenced, 45 seconds at the earliest. The scheduler then places replacements under the same names, and Ruckos LB has already stopped sending connections to the lost replicas.

Upgrades, one replica at a time

You choose how each replica is replaced when you start an upgrade.

Two ways to replace a replica during an upgradeSurge starts a fourth replica on the new image, waits until it is healthy, then stops an old one. In place stops an old replica first and starts its replacement on the new image under the same name. Surge: start the new one first v1v1v1three on the old image v1v1v1v2a fourth starts on the new v2v1v1healthy, so an old one stops In place: stop the old one first v1v1v1three on the old image –v1v1web-1 stops v2v1v1web-1 starts on the new, same name
Either way it is one replica at a time, and each new one must be healthy before the next old one stops.

A new replica that is not healthy after five minutes stops the upgrade and keeps the old ones, and the service says why. Asking again with the old image goes back. A service with a data disk per replica always upgrades in place, since web-2's new image has to start on web-2's disk.

The order follows the service's balancing. With spread, new connections go to the other replicas while one is replaced. With sticky, that replica's clients move once. With primary, the standbys are upgraded first and the primary last.

Databases

For a service with one primary, Ruckos tells each replica its role and the primary's address when it starts. When a new primary is chosen, Ruckos runs the service's promote command in that container, for example REPLICAOF NO ONE for Redis or SELECT pg_promote() for Postgres. Ruckos has no built-in knowledge of either database. The primary's turn in an upgrade is a switchover: it stops, an upgraded standby is promoted, and the old primary comes back upgraded as a standby.

Try it

rctl service create 192.168.1.11 --name web --image web.tar --cpus 0.5 --memory 512M --replicas 3 --store nfs1 --load-balancer web --max-per-host 1

rctl service scale 192.168.1.11 web 5

rctl service upgrade 192.168.1.11 web --image web-2.tar --upgrade surge

More on the Ruckos Microservices page, and on how connections reach the replicas in the load balancer post.

Running a mixed Dell, HPE and Supermicro shop from one console

Fleet control that doesn't care who made the box. Every Ruckos node answers the same API, so a PowerEdge, a ProLiant, a ThinkSystem and a white-box chassis are configured, upgraded and watched the same way, from one screen.

Most shops did not plan to be mixed. A rack of Dell arrived with one project, HPE with the next, a few Supermicro boxes came in for storage, and now every job starts with the question of which tool to open. iDRAC for the Dells, iLO for the HPEs, SSH everywhere, and a spreadsheet to remember which is which.

Ruckos removes the question. The operating system is the same image on every box, and the node API is the same on every box. The server's own identity — manufacturer, model, board, firmware — is read from its firmware and shown in the tools, and then it stops mattering: the disks are listed, partitioned, formatted and shared the same way; the network card, address, DNS and NTP are set the same way; the role — hypervisor, storage, Kubernetes — is given the same way; the build is upgraded, and rolled back if it fails, the same way. rctl, ruckos-v and Lighthouse are three ways to say the same thing to the same API.

There is nothing to log into. Ruckos has no SSH, no RDP, no VNC on a host, and no vendor agent; the API is the only way in, and it is the same API whether the node is a Dell in the rack, a Supermicro in the storage row or a VM on a hypervisor. A new box is a USB stick and a keystroke; after that it is a row in the console like every other row.

One thing stays with the vendor, on purpose. Powering a dead server on, changing BIOS settings and flashing firmware are the job of the lights-out controller — iDRAC, iLO, XClarity — and Ruckos does not pretend otherwise. Keep the lights-out card. Replace everything after power-on.

Previously in this series: installing Ruckos on bare metal, the seven screens that are the same on every vendor's hardware.

Installing Ruckos on bare metal

From a USB stick to a node waiting for its role, in seven screens. Boot it from USB, DVD or PXE; the screens are the same. No driver disk, no RAID-controller dance, no operating system to install first.

Ruckos Linux installs the way a hypervisor should: boot the image, pick a disk, say how much of it the OS gets, reboot. The whole thing is a 155 MB image and three small partitions. The same image boots from a USB stick, a DVD or PXE; this walkthrough uses USB. Here is every screen you will see on a Dell, HPE or Supermicro box, in order.

1. Pick the disk

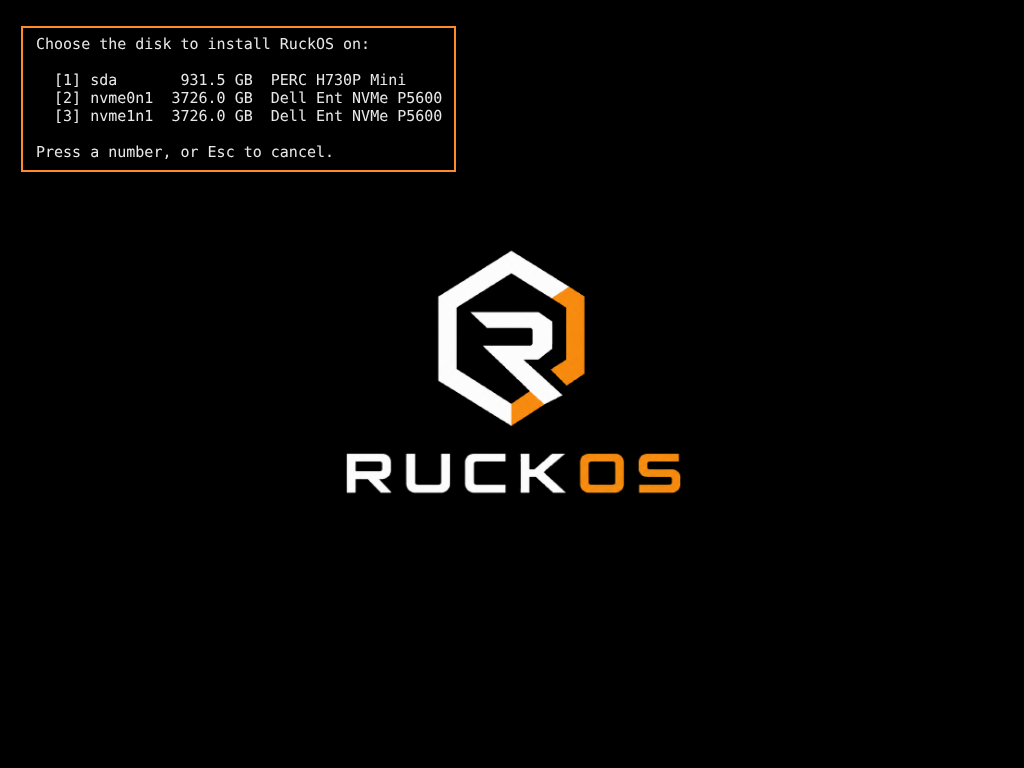
The Ruckos installer listing a PERC virtual disk and two NVMe drives by name, size and model
Every disk the system presents, by name, size and model. The USB stick you booted from is never offered.

Ruckos lists whatever the hardware presents. A RAID controller's virtual disk shows up under its own name (the PERC above), right next to the NVMe drives. Set the controller up however you like in its own menus first; Ruckos installs on what it sees.

2. This screen is skipped on a blank drive.

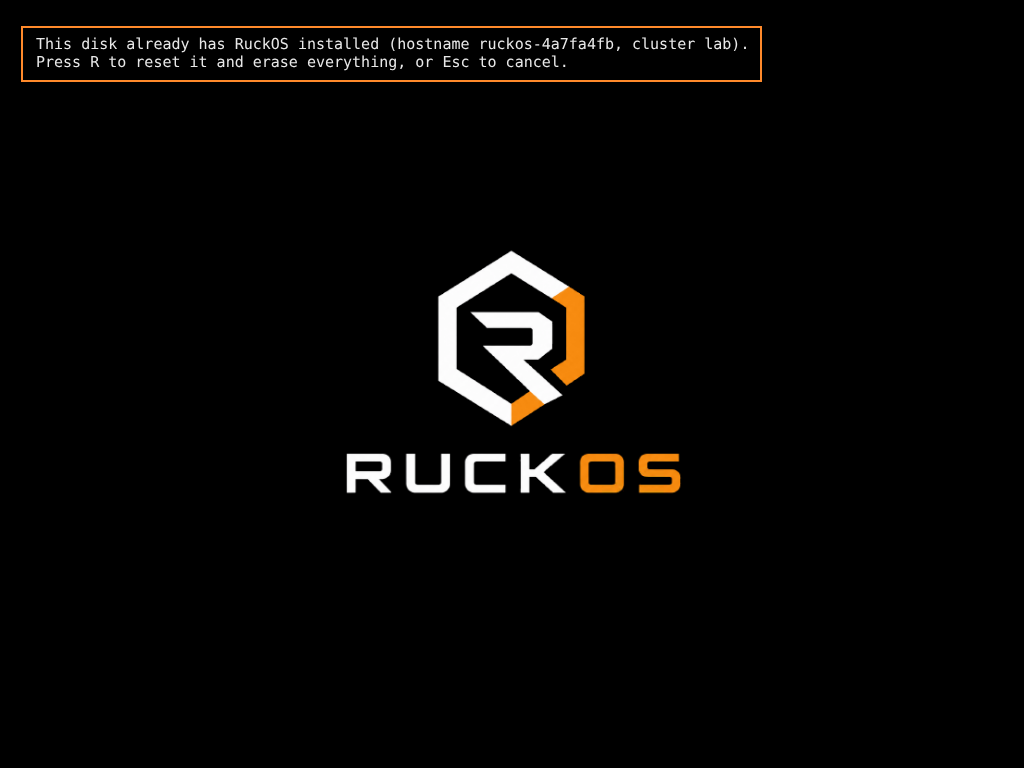
The installer warning that the disk already holds a Ruckos install, naming its hostname and cluster
A disk that already holds Ruckos is named, with the host and cluster it belonged to. R erases it; Esc backs out.

If the disk already holds a Ruckos install, the installer tells you which host it was and which cluster it was in, and waits for R. Esc reboots without touching anything.

3. Decide how much Ruckos gets

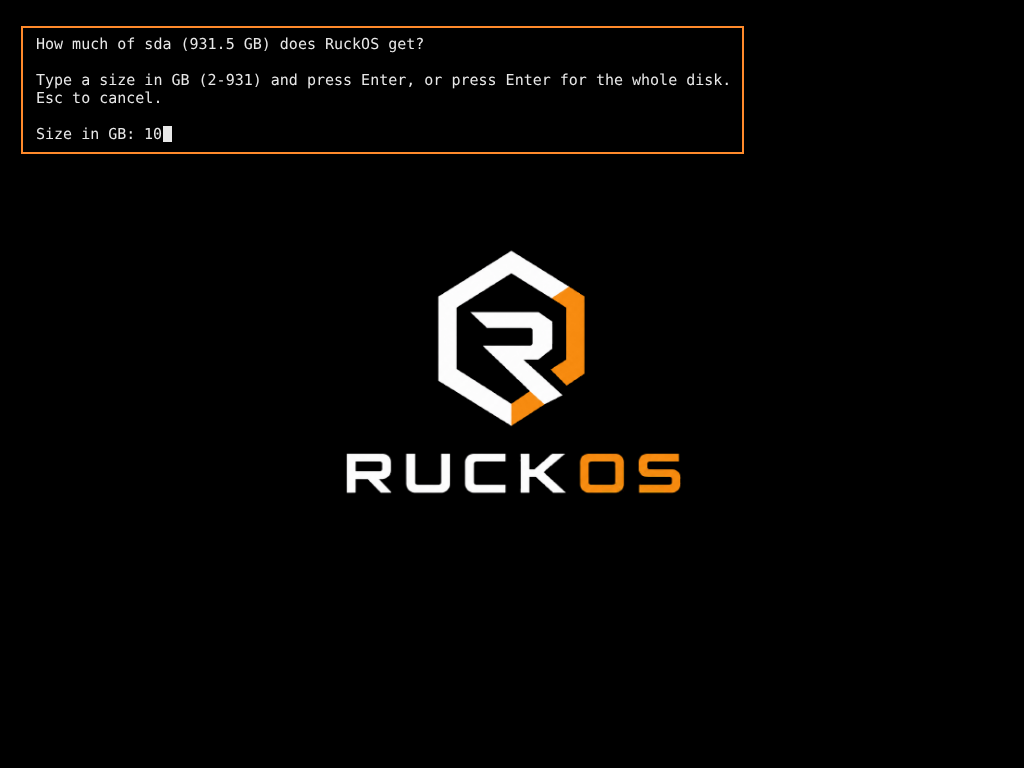
The installer asking how much of the 931 GB disk Ruckos gets, with 10 typed in
10 GB is plenty. The rest of the disk stays free.

Ruckos needs very little: 1 GB for EFI, a STATE partition for its configuration and logs, and a BIOS boot stub. We give it 10 GB and leave the rest of the disk free. That free space is what becomes the VM store on a hypervisor, or the shares on a storage node, later and from a tool, not from this keyboard. Press Enter on its own and Ruckos takes the whole disk, which is right for a Kubernetes node.

4. Install

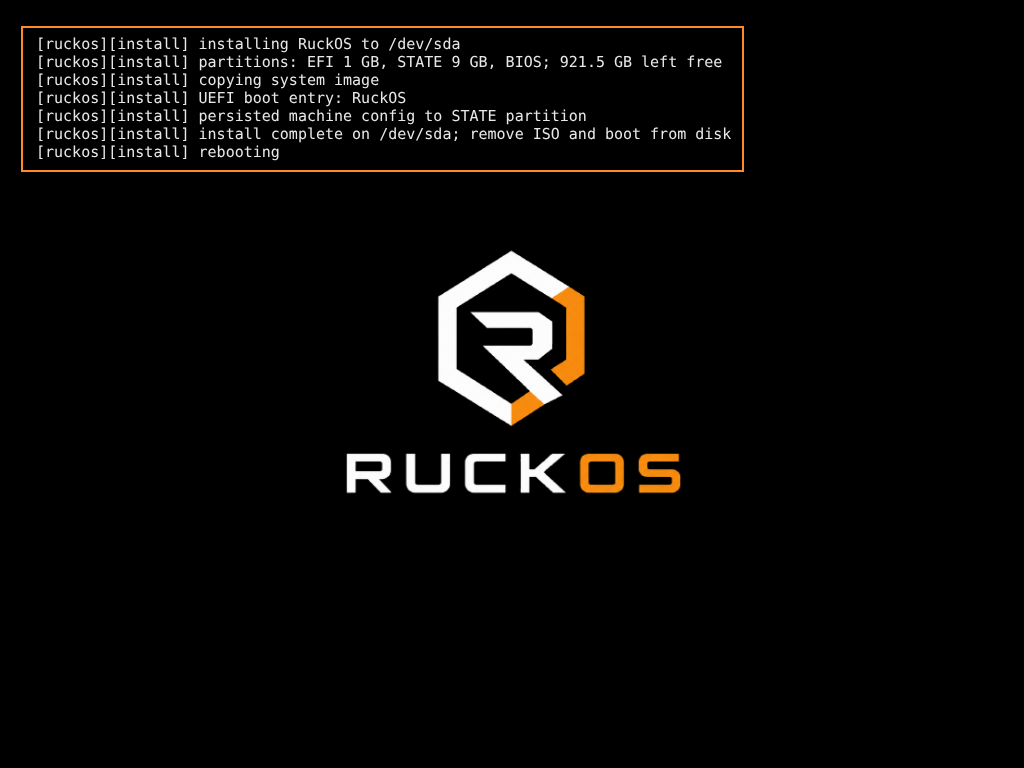
The install log: partitions created, image copied, UEFI boot entry written, rebooting
Partition, copy, write the boot entry, reboot. Seconds, not minutes.

The partitions are created, the image is copied, a UEFI boot entry named RuckOS is written (and GRUB for machines that still boot BIOS), and the node reboots on its own. Pull the USB stick.

5. First boot

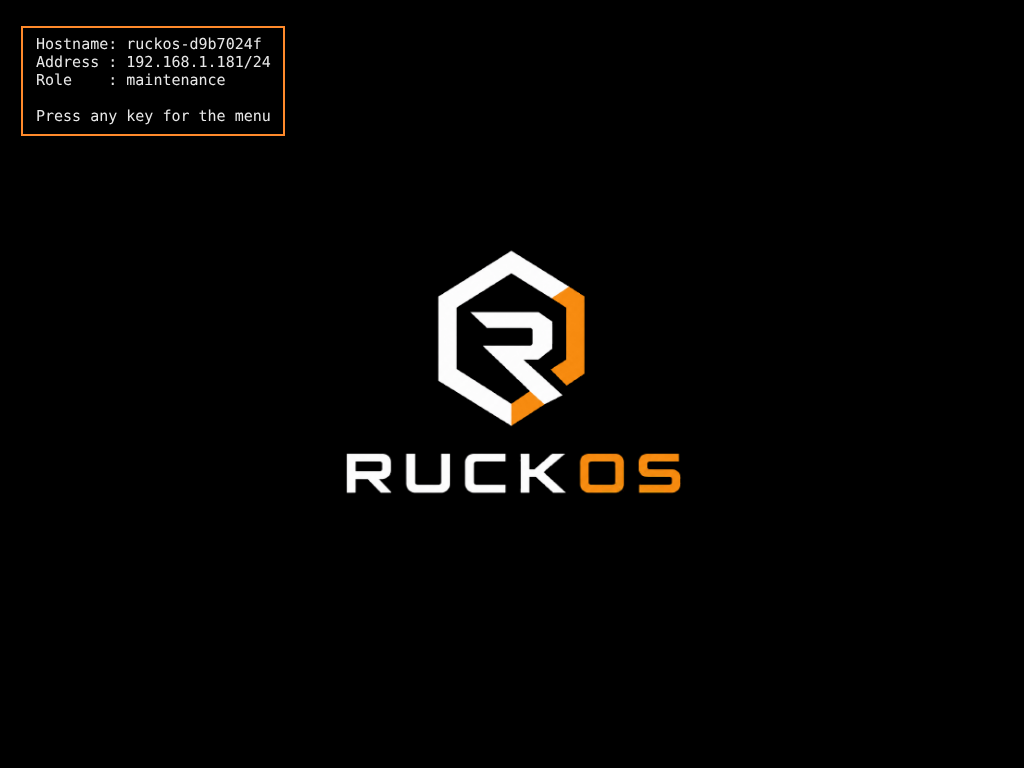
The first-boot status box: hostname, DHCP address, role maintenance, press any key for the menu
Ten seconds after power-on: on the network, API up, waiting for a role.

The node comes up read-only, takes a DHCP address, generates its hostname and sits in the maintenance role. Its API is already listening, so from here on you can leave the console: rctl, Ruckos-V Manager and Lighthouse all see it now.

6. The console menu

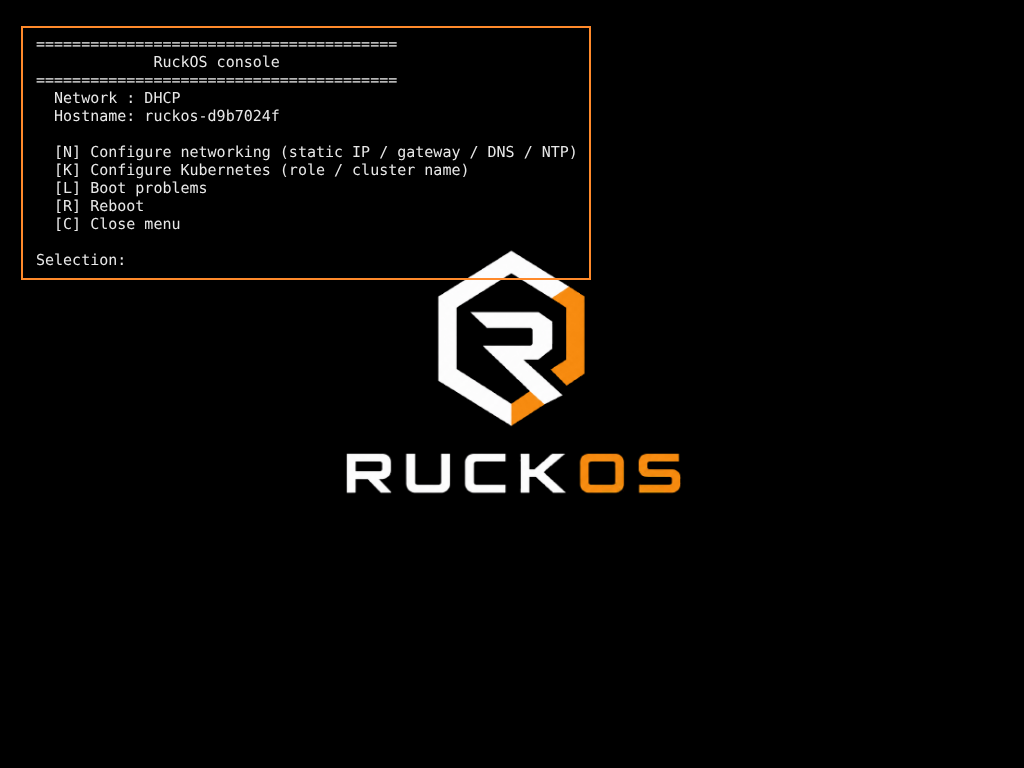
The Ruckos console menu: configure networking, configure role and cluster, boot problems, reboot
Networking, role, boot problems. That is the whole menu.

Press any key and you get the only menu Ruckos has. Static addressing and NTP if DHCP is not how your data center works; the role and cluster name; a list of anything that went wrong this boot. There is no shell behind it.

7. Give it a role

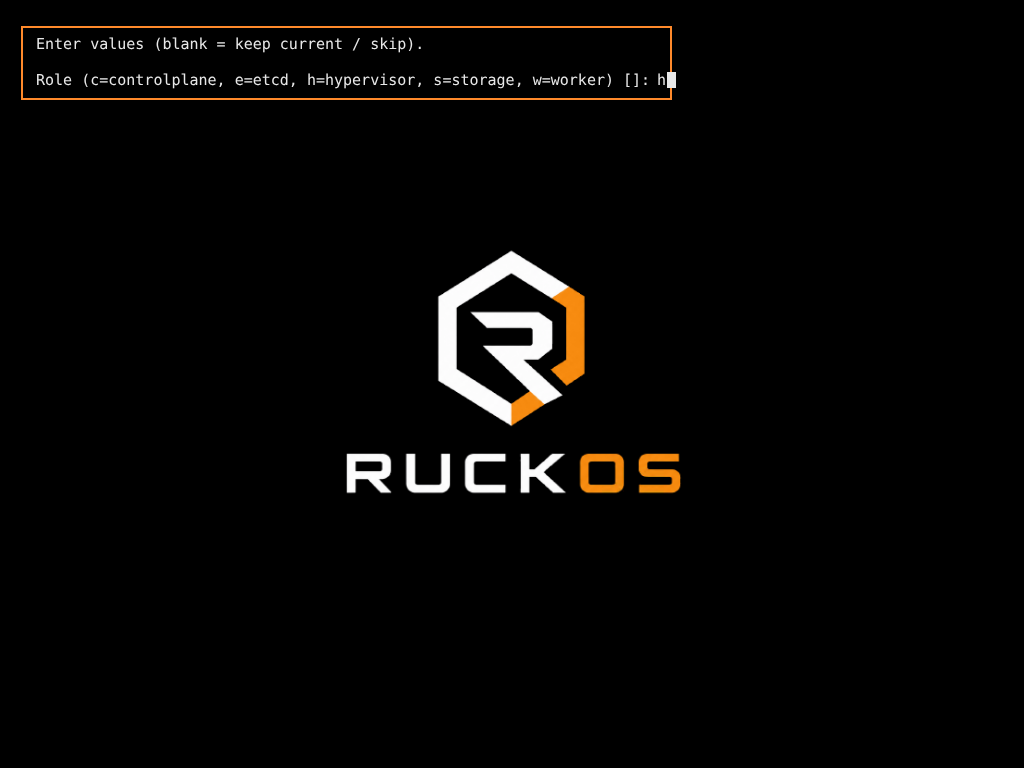
The role prompt: c for control plane, e for etcd, h for hypervisor, s for storage, w for worker
One keystroke. The same image becomes a hypervisor, a storage server or a Kubernetes node.

h makes it a hypervisor; s makes it a storage server that shares the free space over NFS; c, e and w make it a Kubernetes node. You can also set the role from rctl or Lighthouse instead and never open this menu at all.

Next in this series: the hypervisor role, from the free space to the first VM to a three-host cluster, and the storage role, a chassis of NVMe serving every hypervisor.

Rollout GitOps, Observability, and portal

GitOps, ingress, identity, and storage land on the cluster automatically.

rctl bootstrap platform --site config/site.yaml

RapidHire: AI-powered candidate-to-job matching

RapidHire matches candidates to job postings using a Neo4j graph, contextual skill weighting, and LLM-powered analysis — independent resume and job uploads, on-demand scoring. Watch the demo below.

RapidHire pairs a Neo4j graph database with contextual skill extraction and vector search to surface the strongest candidate-to-job matches.

Contextual, weighted matching

Skills are extracted with importance weighting — critical, important, or preferred — based on how they appear in the job description, then matched against candidate profiles using cosine similarity over dimensional embeddings. Matches are ranked by critical-skill coverage first, overall weighted score second.

Built for scale and privacy

PII is scrubbed before any resume text reaches an LLM, bulk uploads are processed independently of job assignment, and the LLM/embedding backend is swappable — Ollama, OpenAI, Gemini, or AWS Bedrock — so teams can run fully on-prem if required.

Self-service environments

IDP: Ruckos Cloud adds a developer portal as part of the platform. It provisions Postgres, MySQL, Redis, Neo4j, and full .NET API scaffolds straight into a namespace that belongs to you. Watch the demo below.

An Enterprise-grade self-service developer portal that hands each developer their own Kubernetes namespace and a catalog of resources they can provision into it on demand — Postgres, MySQL, Redis, Neo4j, or a ready-to-run .NET API scaffold — without opening a ticket or waiting on a platform engineer.

From provision to IDE in one step

Once a resource is provisioned, the portal can drop the generated project straight into a Git repo through a GitHub App integration and hand you a one-click "open in VS Code" link.

Identity-aware from the start

Access is brokered through OIDC via Keycloak, so every provisioning action is tied to a real identity rather than a shared service account. Internal Developer Portal ships as a Helm chart, so it deploys into your cluster.

Provision Raft

Setup Ruckos nodes for cluster quorum and control-plane readiness.

rctl.exe bootstrap etcd --site config/raft/raft.yaml

Provision 9-node cluster

Deploy and configure a 9-node external etcd cluster with the standard discovery flow.

rctl.exe bootstrap --site config/ruckos/ruckos.yaml --type external

20 Kubernetes best practices for 2026

VMware's Broadcom era is pushing enterprises toward private cloud, microservices, and local AI

Steep license increases since the Broadcom acquisition are accelerating a shift a lot of teams were already making: containerized, GitOps-run private clouds — and now local LLM inference on GPU-dense hardware from Dell and HPE.

Broadcom's acquisition of VMware rebuilt the commercial model around subscription bundles like VMware Cloud Foundation, priced on a per-core basis with a 16-core-per-processor minimum, and pushed customers toward packaged suites instead of à la carte purchasing. The result has been sticker shock: industry surveys put the share of organizations actively shrinking their VMware footprint in the high 80s percent, with some renewal quotes reported north of 1,000% over prior terms once minimum commitments and bundling are factored in.

Microservices and private cloud, not just cost control

The response isn't only a negotiation tactic. Platform teams are using the forced renewal conversation as cover to do work they wanted to do anyway: breaking monolithic, VM-hosted applications into containerized microservices and running them on a self-operated private cloud, so the exit from one vendor doesn't just walk into another one. GitOps delivery (Argo CD, Flux), the Gateway API, and policy-as-code — the same practices in our Kubernetes best-practices list above — are becoming the default operating model in place of click-ops through vCenter.

AI is riding the same wave

That modernization push is colliding with a second one: running AI workloads in-house instead of shipping proprietary data to a third-party API. Open-weight models — Llama, Mistral, Qwen, DeepSeek, and others — are now good enough for a large share of internal use cases, and serving them locally with vLLM, Ollama, or TGI keeps sensitive data inside the perimeter and turns a per-token bill into a fixed infrastructure cost.

The hardware catching up

Server vendors have followed. Dell's PowerEdge R760xa packs up to four double-width GPUs into a mainstream rack form factor, while the XE-series scales to eight GPUs per node for larger models; HPE's ProLiant DL380a Gen11 targets the same workload with validated NVIDIA configurations up to H100/H200 and L40S. Paired with a Kubernetes-based private cloud, that hardware turns local LLM inference into just another workload on the same GitOps-managed clusters running everything else — which is exactly the seam platforms like Ruckos and lighthouse are built to sit in.